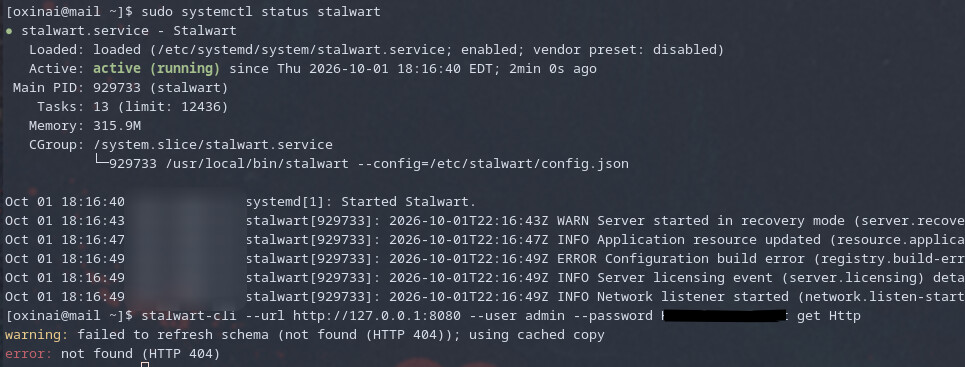
I hit update applications on the webui and I suspect something silently failed on my end, as I can now no longer access anything that would be under http/s, including /admin, /account, and /api. Further, this has also killed the cli’s access. Everything results in a 404, but formatted in JSON by the stalwart server; also I can still send/receive emails.
stalwart version: 0.16.23
most recent webui: 1.0.11
I understand that topics in this category are triaged by a bot first but a human reply will follow up. If I’d prefer a human-only reply, I’ll add the no-ai tag to my topic.
Found it. This is a documented upgrade guide scenario. Let me read the full section for the exact recovery steps.
The most likely cause is that “Update applications” tried to fetch a fresh WebUI bundle and that download failed (or the previous cached bundle was discarded), leaving no application bundle unpacked to serve /admin, /account, etc. This is a documented failure mode: on update, Stalwart discards the cached bundle when the Application record’s resourceUrl changes/updates, then re-downloads from https://github.com/stalwartlabs/webui/releases/latest/; if that fetch fails and no previous bundle remains cached, every request under a WebUI mount path returns 404 Not Found, and the server still answers with a JSON 404 body because that’s how the HTTP layer reports “not found” on any unmatched route, including /api sub-paths handled by the JMAP management API.
To recover:
Confirm the host running Stalwart has outbound HTTPS access to github.com and objects.githubusercontent.com (this is required for the WebUI bundle download).
Restart the Stalwart service. A restart forces the applications manager to attempt the unpack again; if the previous bundle blob is still present it will be served while a new fetch is retried on schedule.
If outbound internet access from that host is intentionally restricted, host the WebUI bundle internally and point the WebUI’s Application object’s resourceUrl field at that internal HTTPS location, then trigger the “Update applications” action again.
If you’re fully locked out (CLI and WebUI both unreachable), start the server in recovery mode (STALWART_RECOVERY_MODE=1), which re-enables the HTTP management listener on port 8080 regardless of the current application/bundle state, so you can inspect and fix the Application record.
The /api 404 is expected on 0.16: nothing is served at the bare path since the REST API was replaced by JMAP. The 404s on /admin and /account mean no WebUI bundle is mounted, and at startup the server logs the reason as a resource.error, “Failed to unpack application for prefixes: admin, account”, followed by a download error, an HTTP status, or an unpack directory it can’t write to. What does that line say on yours?
It’s usually the download. The bundle comes from GitHub, so the server needs outbound HTTPS to github.com and its asset hosts; once that works, run stalwart-cli create action/UpdateApps or restart. If the server can’t reach GitHub at all, download webui.zip yourself and set the Application’s resourceUrl to file:///path/to/webui.zip. That also works in recovery mode against http://127.0.0.1:8080. Did you click Update applications before or after upgrading to 0.16.23? Before 0.16.23 a failed update threw away the working bundle; since then the old one stays in service.
The CLI doesn’t touch the WebUI at all (it talks to /jmap and /api/schema), so its 404 is a separate problem. Usually STALWART_URL carries a path such as https://host/admin, or it’s a v0.15 stalwart-cli. Post the exact command and its output with --debug.
I waited till after the update was running before hitting the Update applications button. I’m not sure if it might have been beefed before I tried to do the app update, as there’s nothing in my logs about anything, until suddenly a bunch of the following appears:
If i send out a stalwart-cli create Action/ReloadSettings --debug, I get back:
[debug] -> GET https://mail.example.com/api/schema
[debug] <- GET https://mail.example.com/api/schema status=404 Not Found content-type=application/problem+json content-length=76 content-encoding=identity
warning: failed to refresh schema (not found (HTTP 404)); using cached copy
[debug] -> GET https://mail.example.com/jmap/session
[debug] <- GET https://mail.example.com/jmap/session status=404 Not Found content-type=application/problem+json content-length=76 content-encoding=identity
error: not found (HTTP 404)
also the only thing that shows up in the journalctl for HTTP events is:
Sep 24 14:45:39 mail.example.com stalwart[388676]: X-Forwarded-For header is missing
Sep 24 14:45:39 mail.example.com stalwart[388676]: Expression evaluation result
Sep 24 14:45:39 mail.example.com stalwart[388676]: HTTP response body
On the upside here, my mailserver is still mail-serving, just not web-serving
Just wondering if there is a folder I can unzip the webapp to in an attempt to get some sort of access to stuff again? While its lovely having email, everything in the DAV space is hiding behind a lack of http/s.
I pointed you at the wrong thing last time. A 76-byte application/problem+json 404 on every path, /jmap/session included, is what the HTTP access rule (allowedEndpoints) returns when it refuses a request. A missing WebUI bundle gives a longer error and has no effect on /jmap/session. The “Expression evaluation result” line in your journal is that rule being evaluated. Update applications doesn’t touch it, so I suspect it was already there and the timing is a coincidence.
Requests from loopback skip the rule, so run this on the server itself and post the allowedEndpoints value:
Recovery mode turns the rule off too, but it only listens on plain http://127.0.0.1:8080, so that’s the URL to use while it’s running. If /admin still 404s once /jmap/session answers, that part is the bundle. The server unpacks the zip itself and ignores loose files, so a file:// resourceUrl pointing at webui.zip is how to feed it one.
Also turn off “Use Forwarded IP” under the HTTP settings unless a proxy really sits in front of 443; that’s where the X-Forwarded-For warnings come from. With it on, any client can write 127.0.0.1 in that header and get the same loopback exemption.
The journal should then show “Port 8080 is open for troubleshooting and recovery”. If that line is missing, recovery mode didn’t engage, and that would also explain the 404s you got earlier when you thought it was on. With it running the access rule is off, so on the server itself:
Then stop the service, take both lines out of the env file and start it normally. Leave the Postgres tables alone: the settings are stored encoded and have to go through the API. The error from https://127.0.0.1 happened at the connection level, before any rule was evaluated, so it doesn’t need chasing once this works.
In recovery mode Stalwart only listens on plain HTTP on port 8080, nothing on 443, and the endpoint access rule is switched off. So if the 404 comes from https:// on your domain, it’s being answered by some other process: another Stalwart instance or container, an old service, or a proxy. A 404 for /admin on port 8080 would be something else again (the WebUI bundle), so I need to know which of the two you’re hitting. The screenshot is too small to read; can you paste the exact URL or command that gave the 404, plus the output of these, run on the server while it’s in recovery mode:
curl -si http://127.0.0.1:8080/jmap/session
ss -ltnp | grep -E ':(443|8080)\b'
Not 100% sure what resolved things, but at some point in the past, I’d set the point to 9090, to fix the issue I was having with crowdsec eating 8080, but everything got set back to 8080 after I upgraded to 0.16 a while back.
Good news, something in the last few commands DID fix things. Thanks for the help! (bad news, not a clue what it specifically was)
Glad it’s back. CrowdSec’s API also listens on 8080 by default, the same port recovery mode uses, so it may well have been what answered some of those 404s. If you need recovery mode again, add STALWART_RECOVERY_MODE_PORT=9090 next to the other two lines. And make sure STALWART_RECOVERY_MODE and STALWART_RECOVERY_ADMIN are gone from /etc/stalwart/stalwart.env now; otherwise the next restart puts you back in recovery mode with that admin password still sitting in the file. Details: Environment variables | Stalwart